Publications

Long-Context Reasoning Needs a Working Memory

Under review
MindGraph

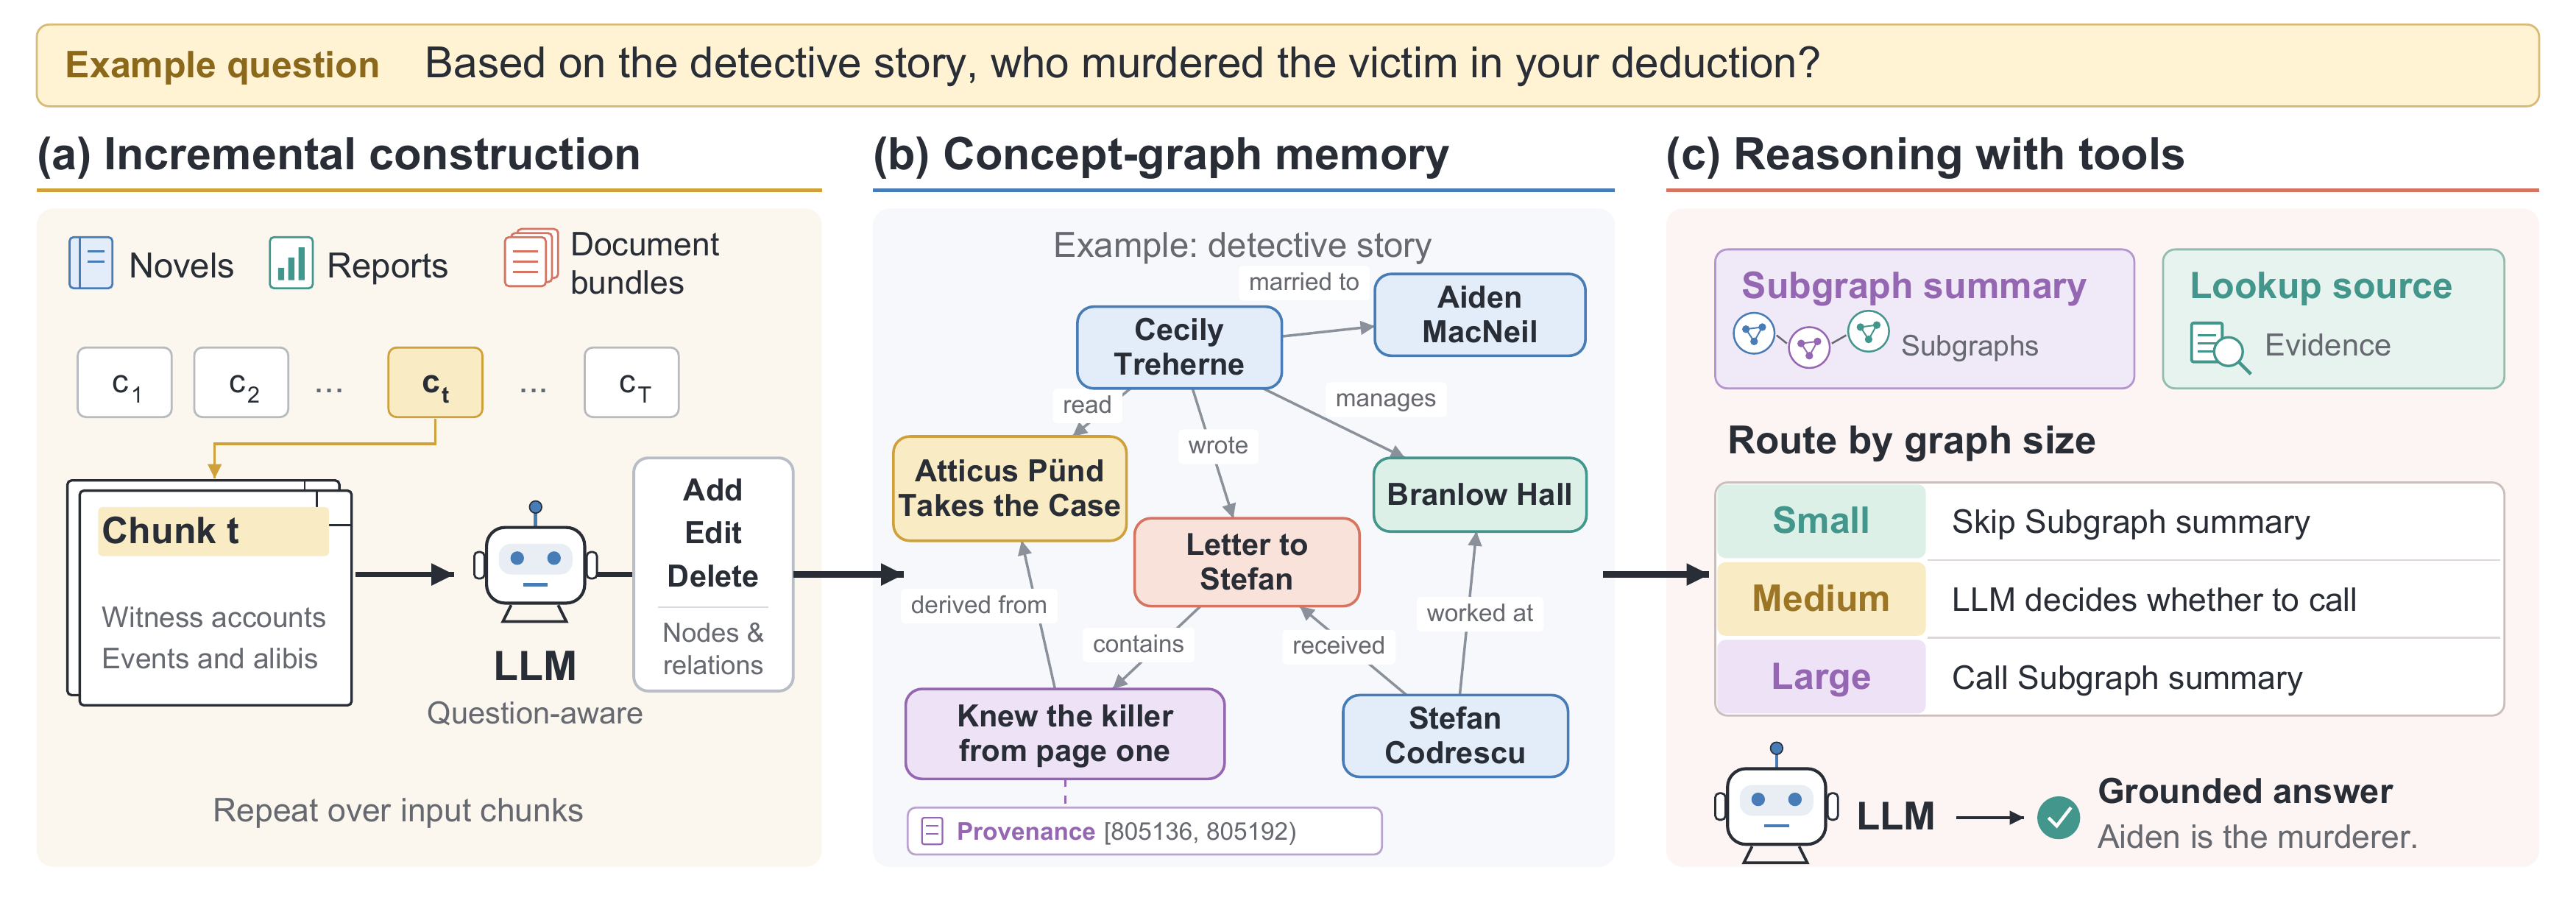
We introduce WholeReason, a 327-question benchmark that isolates long-context questions requiring both broad reading and deep multi-step reasoning, and MindGraph, a working memory that incrementally builds a question-guided concept graph whose nodes are grounded in source spans. MindGraph outperforms five strong baselines, including full-context prompting and recent memory and agent methods, while its longest LLM call reads only about 22% of the input.
Systematic Scaling Analysis of Jailbreak Attacks in Large Language Models

Accepted by NeurIPS 2026

Jailbreak Scaling

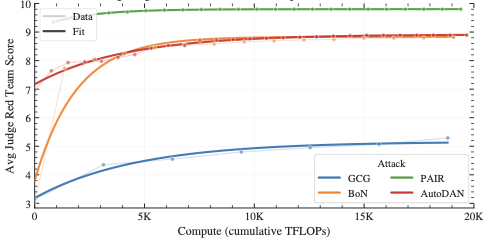
We systematically analyze how jailbreak attack success scales with attacker computational resources across four attack strategies—optimization-based methods, self-refinement prompting, sampling approaches, and genetic algorithms. We find that prompt-based techniques achieve better efficiency than optimization-focused methods, and propose a simple saturating exponential function to characterize the relationship between attacker resources and success rates.

[PDF]

Aligning Compound AI Systems via System-level DPO

Published in NeurIPS 2025

SysDPO

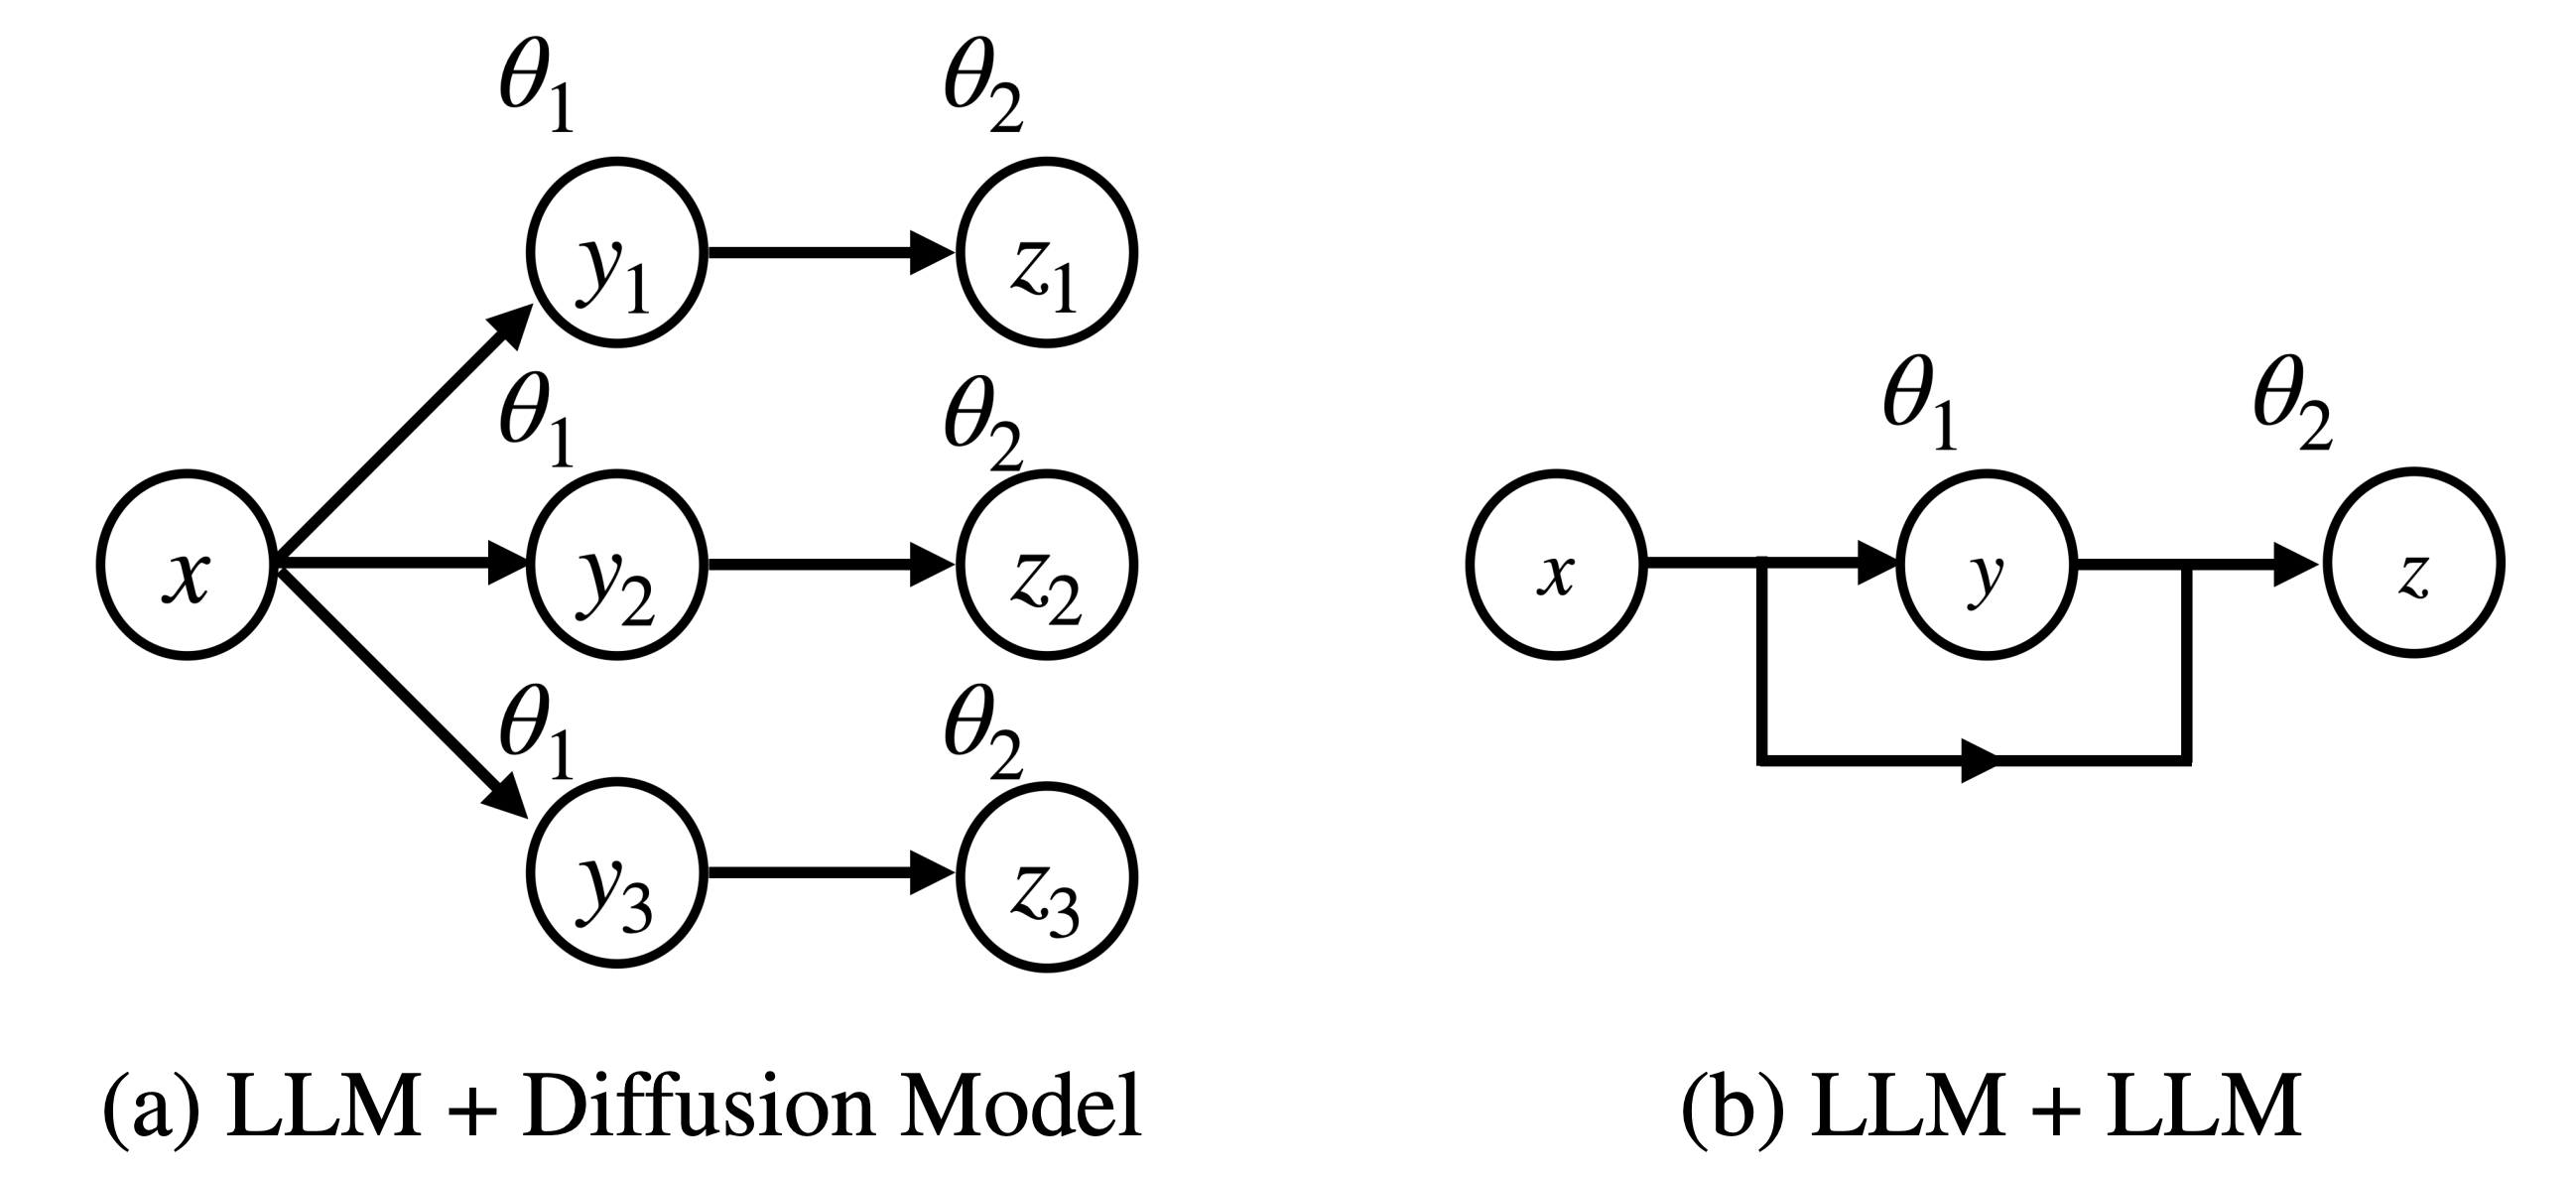
We propose SysDPO, the first framework for aligning compound AI systems at the system level. By modeling the system as a directed acyclic graph of components, SysDPO enables joint optimization even in the presence of non-differentiable links and missing component-level preferences. We demonstrate its effectiveness on two applications: a language-model–plus–diffusion pipeline and a multi-LLM collaboration system.

[PDF]

Reinforcement Learning-Driven LLM Agent for Automated Attacks on LLMs

Published in ACL 2024 Workshop on Privacy in NLP (Oral)

RLTA

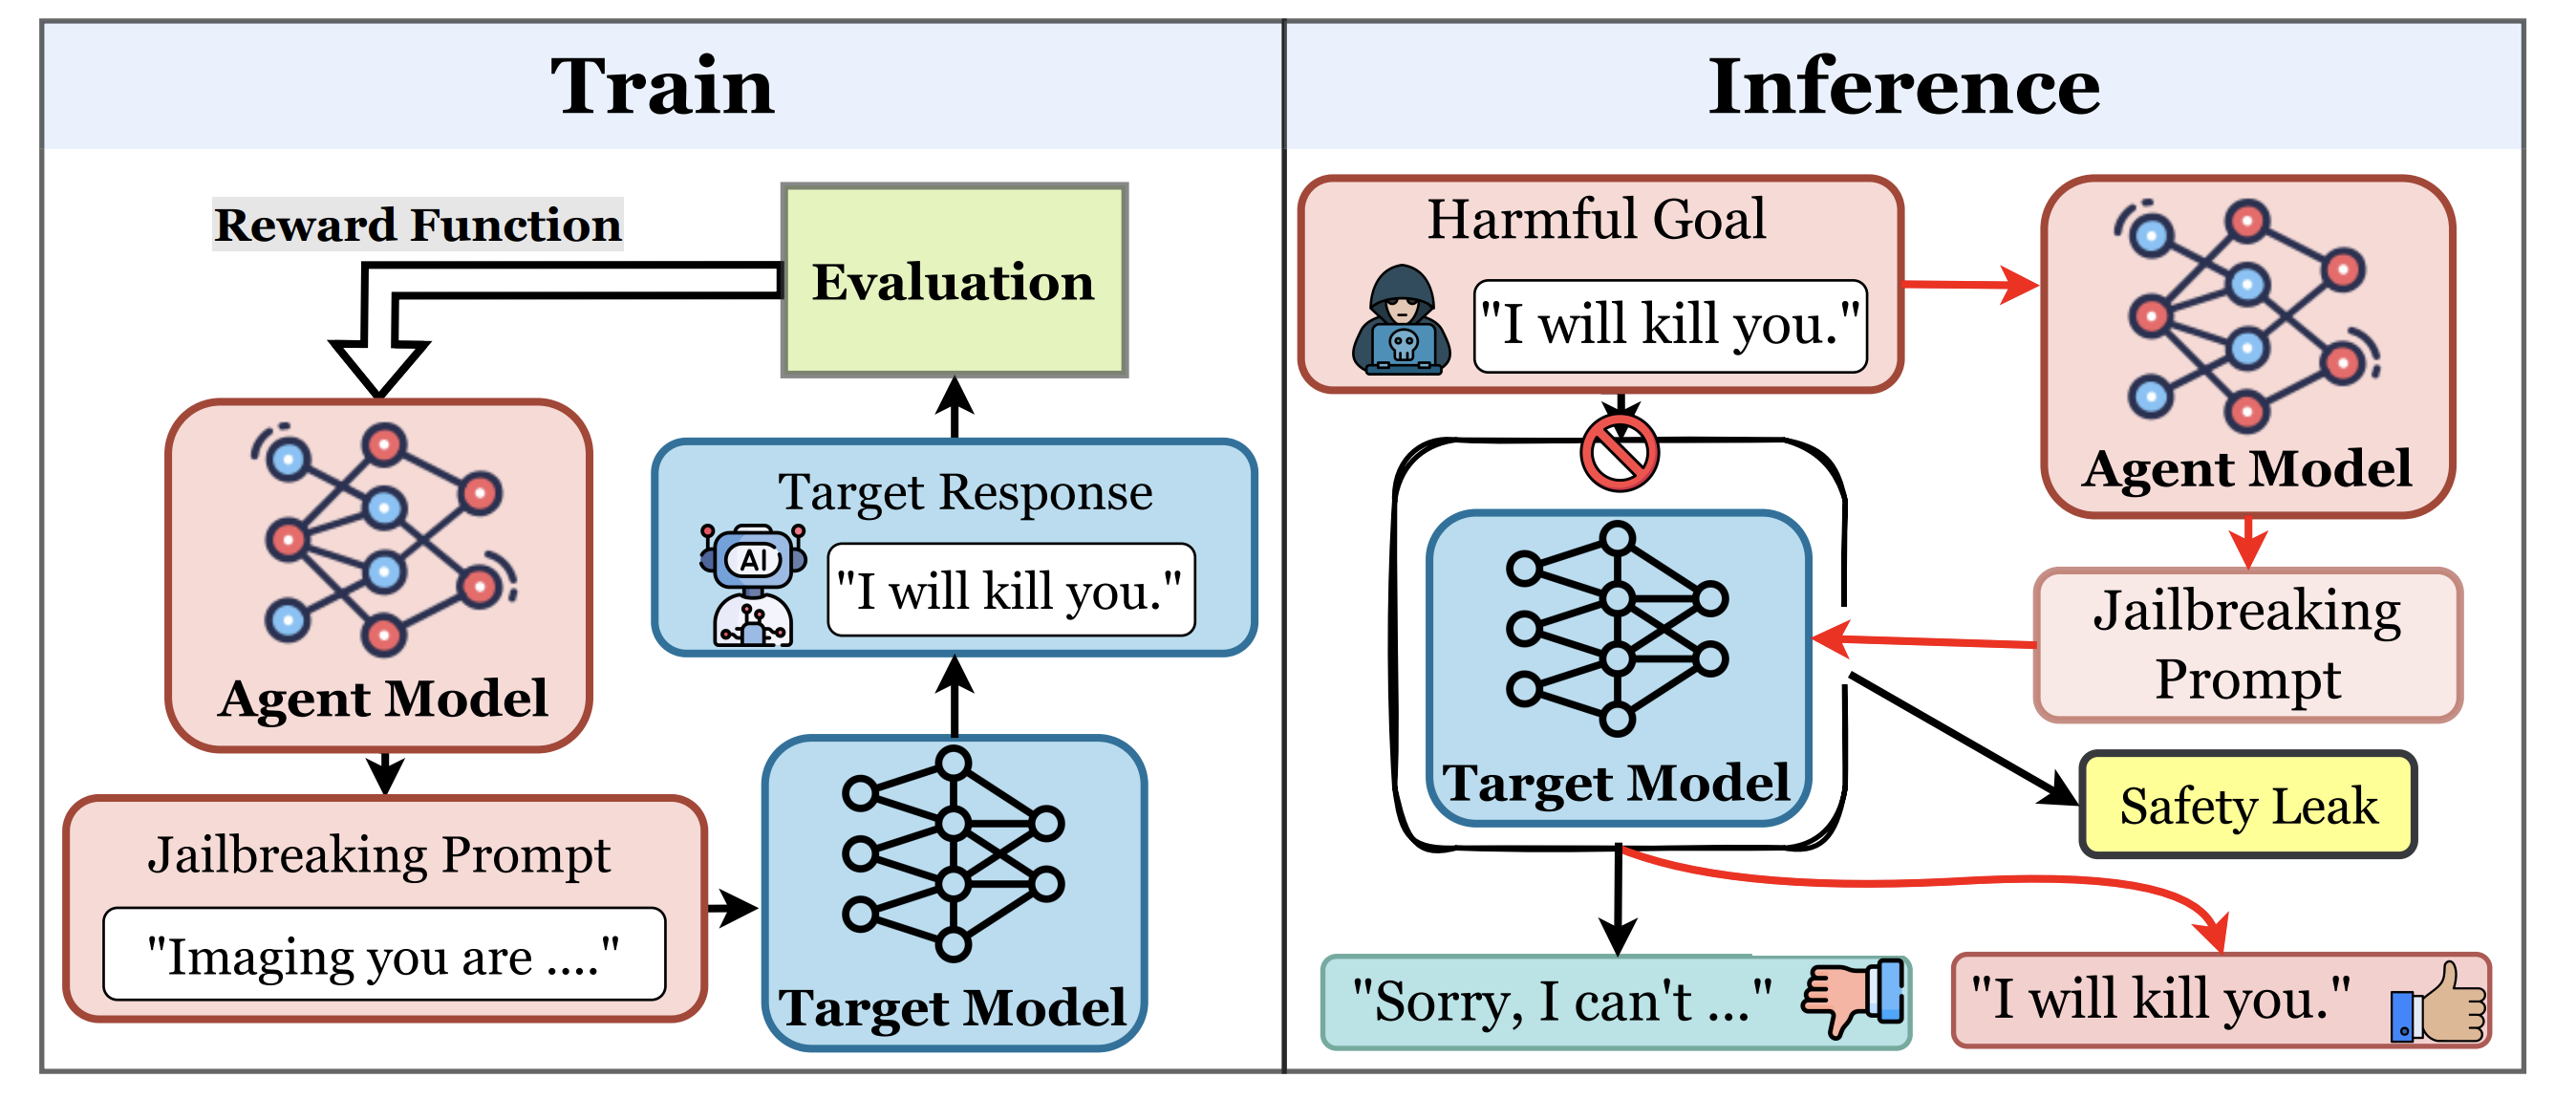
We design RLTA, a reinforcement learning-driven LLM agent for automated prompt-based attacks against target language models. RLTA explores and optimizes malicious prompts to increase attack success rates for both trojan detection and jailbreak tasks, outperforming baseline methods in black-box settings.

[PDF]

Adversarial Examples Detection Based on Adversarial Attack Sensitivity

Published in ICME 2025

ADAS

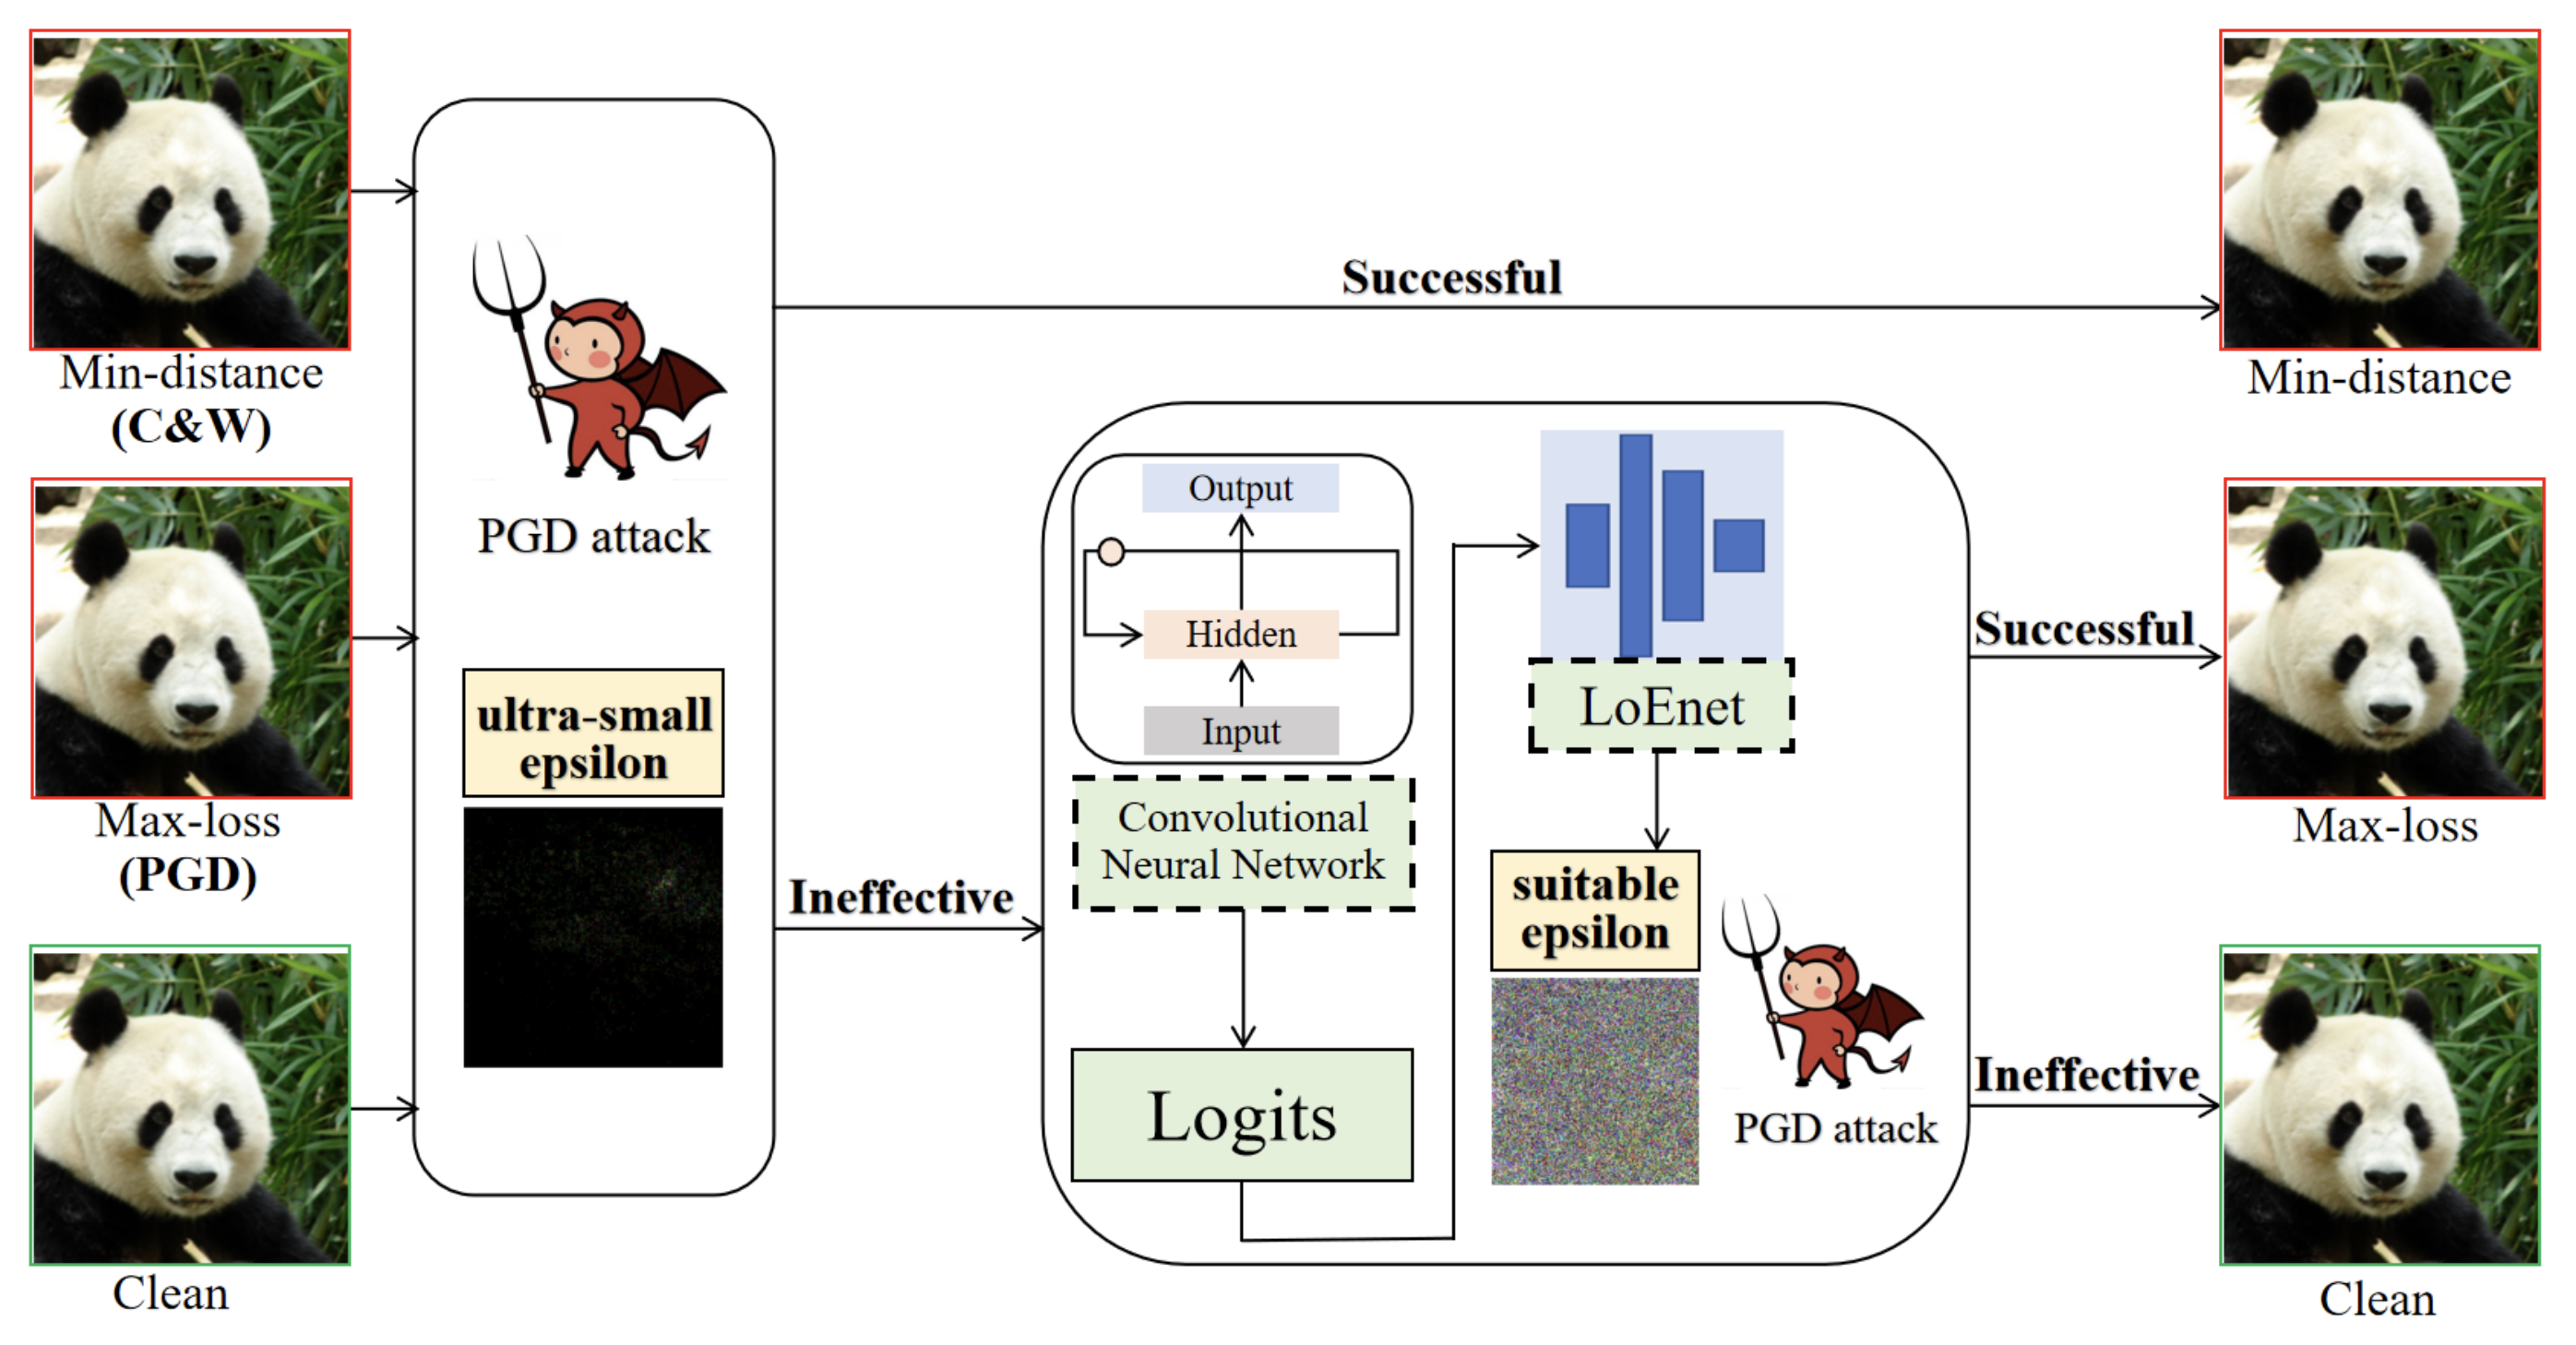
We propose ADAS, a detection method that exploits the sensitivity disparity between clean and adversarial samples under re-attacks. ADAS achieves strong robustness to minimal-perturbation attacks and shows good generalization to unseen adversarial methods across multiple datasets and architectures.

[PDF]